The classic pipeline is grep → sed → awk, but you do not need all three. grep filters lines; sed edits streams; awk treats fields and can sum or group — the comparison every junior admin searches before writing a ten-line script.
grep — keep matching lines
Regex, case, context lines — first tool for ERROR in a log.
bashgrep
grep -E 'error|crit' /var/log/syslog | tail
zgrep 'POST /api' access.log.gz | head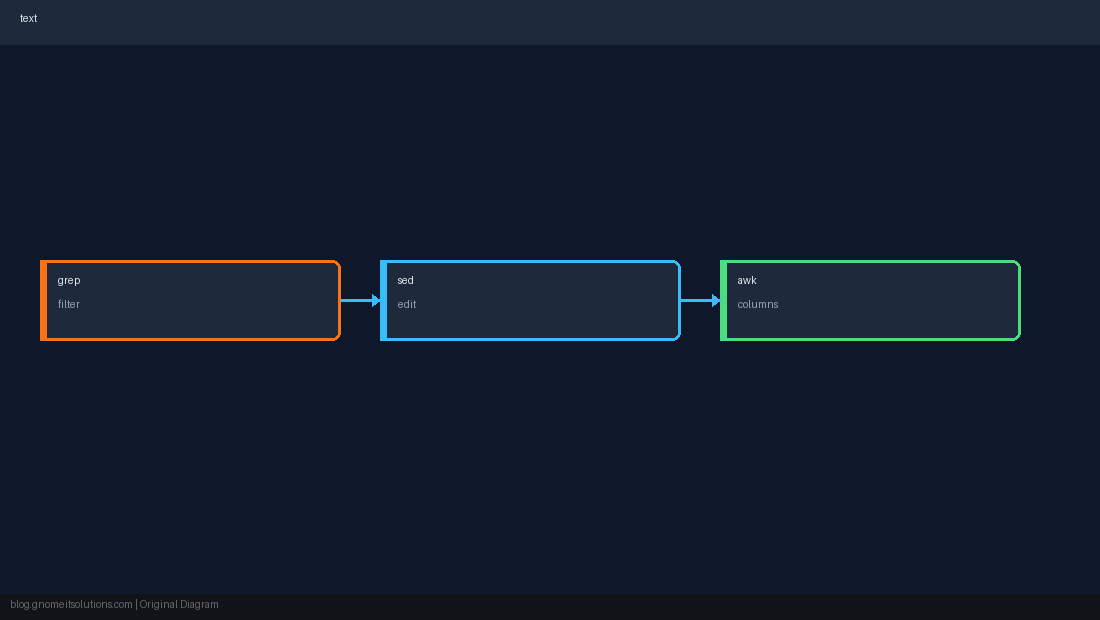
sed — transform text in flight
Substitute, delete, print range — often one-liners without a full script.
bashsed
sed -n '1,20p' file.conf
sed 's/http:/https:/g' urls.txt | headawk — fields and reports
Default FS whitespace; perfect for df, ss, or Apache combined logs.
bashawk
df -hP | awk 'NR>1 {print $1, $5}'
awk -F: '$3 == 0 {print $1}' /etc/groupWhen to combine vs pick one
Filter first (grep), normalize (sed), aggregate last (awk). For JSON logs, consider jq instead.
NoteAvoid
grep | sed | awk on gigabyte files without narrowing first — use tail, time range, or indexed logs.Quick Reference
- Match lines:
grep - Edit stream:
sed - Columns / math:
awk
Related tutorials
Diagrams are original illustrations by Gnome IT Solutions. Tutorial text © Gnome IT Solutions.